Google’s own AI optimization guide says maintaining an llms.txt file “will neither harm nor help your site’s visibility or rankings” in Google Search. That single sentence, published as part of Google’s May 2026 guidance, undercuts a good chunk of the content that’s been written about llms.txt over the past two years, much of which treats it as an SEO checklist item on par with a sitemap. Version 2 of the specification, released August 10, is a real, useful update, but only for the audience it was built for, and being honest about who that audience is matters more than most of the coverage of this release has bothered to be.
What llms.txt Does
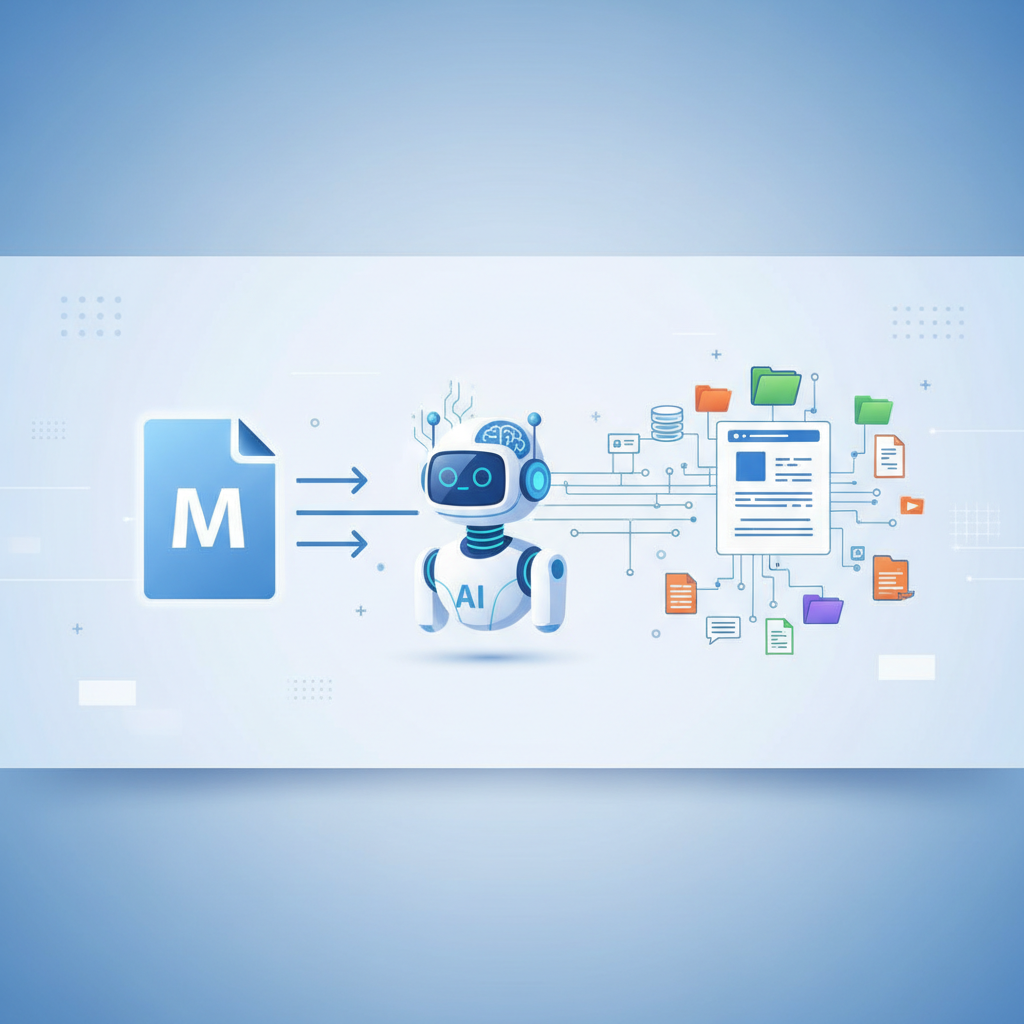
llms.txt is a plain text file at a site’s root, built on Markdown, that’s meant to help AI systems understand a site’s structure and locate clean, parseable versions of its content without having to strip a full HTML page down to its meaningful text. Jeremy Howard of Answer.AI created the format, and it’s built around a simple idea: LLMs work more efficiently with Markdown than with HTML, so a file that hands them Markdown directly, along with a map of what’s where, saves the system work compared to scraping a rendered page.
Adoption has been real, if concentrated. Thousands of sites publish an llms.txt file at this point, hosting platforms like Mintlify generate one automatically for every site they host, and major AI labs including Anthropic, OpenAI, and Google’s own Gemini team publish llms.txt files for their developer documentation. Chrome’s Lighthouse tool added an “Agentic Browsing” audit category in its 13.3 release that checks whether a site provides one, a signal that browser and tooling vendors consider this a real, ongoing standard rather than a fad that’s already fading.
What Changed in Version 2
The first version of llms.txt supported exactly one pattern for linking a page to its Markdown equivalent: appending .md to the end of the filename, so /docs/tutorial.html pointed to /docs/tutorial.html.md. Version 2 adds a second, more common pattern where the extension is replaced rather than appended, producing /docs/tutorial.md instead. That sounds minor, but it matches how most documentation platforms already structure their Markdown source files, which removes a real point of friction for sites that wanted to adopt the spec but didn’t want to restructure their URLs to match V1’s specific convention.
The more substantial change is formal link relations that let automated tooling discover the relationship between a page, its Markdown version, and the site’s llms.txt file without a human having to configure anything beyond adding the links. Two implementation paths exist: HTML pages can include a rel="alternate" link with type="text/markdown" pointing to the Markdown version, plus a rel="describedby" link pointing back to llms.txt itself; alternatively, servers or CDNs can add the same relationships as HTTP Link response headers, which works even for non-HTML files and requires no template changes at all. That header-based option is the more interesting one operationally, since it means a hosting platform or CDN could add llms.txt discoverability to every page on a site in one configuration change, without anyone touching the site’s templates.
Who This Helps
The honest answer is: developer documentation, API references, and any site whose primary non-human visitors are coding agents and IDE tools rather than search-answer engines. AI coding assistants like Cursor, GitHub Copilot, and Claude retrieve documentation in real time while a developer is working, and llms.txt helps them fetch the right page with less token waste and less parsing overhead than scraping a full HTML page with navigation, ads, and boilerplate stripped out on the fly. For a SaaS product with API docs, or an open-source project with a documentation site, that’s a genuine efficiency gain for the AI tools developers already use against that content, and it’s worth noting the gain compounds as an API surface grows, since a larger docs site means more pages an agent would otherwise have to parse from raw HTML on every request.
For a typical small business website selling hosting, products, or services, none of that applies. There’s no coding agent trying to parse a product page’s Markdown structure to call an API. The audience an llms.txt file is built to serve simply isn’t visiting that kind of site in the way the format was designed around, and Google’s explicit statement that it doesn’t move the needle for AI Overviews, AI Mode, or classic search rankings removes the one alternative justification a business owner might reach for.
Two Sites, Two Different Answers
The clearest way to see the split is to compare two hypothetical AllCloudHost customers side by side. The first runs a PrestaShop storefront selling physical goods. Its visitors are shoppers and, occasionally, an AI answer engine summarizing a product review. No coding agent has any reason to fetch that store’s Markdown, because there’s no API surface for a developer tool to interact with. For that site, an llms.txt file is a file that sits unread, and the hour spent implementing it would do more for search visibility if spent writing a genuinely useful product description or fixing a slow page instead.
The second customer runs a small SaaS tool with a public API and a documentation site, hosted on a VPS. Developers integrating with that API increasingly do so with an AI coding assistant open, asking it to read the docs and write the integration code. For that site, llms.txt V2’s header-based linking is worth the half hour it takes: it reduces how much irrelevant HTML the coding assistant has to wade through, and it plugs into tooling, like Lighthouse’s Agentic Browsing check, that developers evaluating the API might actually run before committing to it. Same specification, same implementation cost, genuinely different payoff, because the audience that benefits is defined by function, not by industry.
Where the Confusion Comes From
Part of why llms.txt gets over-recommended is a genuine, if imprecise, category error: it sounds like it should be part of the same family as robots.txt or a sitemap, things every site is told to have as basic hygiene. robots.txt controls crawler access and a sitemap helps search engines discover pages, both of which have a direct, well-documented effect on how a site gets indexed. llms.txt does neither of those things. It’s closer to an API contract for a narrow category of automated tools than it is to a discoverability signal for search or AI answer engines, and conflating the two leads to guides that recommend it universally when the actual beneficiary list is much shorter.
The specification itself is also still evolving. It remains open for community feedback on GitHub, and the maintainers have been explicit that syntax could shift again before the format reaches a fully stable release. That’s a reasonable state for a two-year-old, community-driven standard to be in, but it’s another reason treating it as a settled SEO requirement gets ahead of where the format is.
A Practical Way to Decide
Rather than following blanket advice either direction, the decision comes down to one question: does an AI coding tool, agent framework, or developer-facing integration meaningfully interact with your content today? If your site is documentation, an API reference, an SDK, or a developer-facing product, implementing V2’s header-based linking is a low-effort, genuinely useful addition, and most SEO plugins including Yoast and Rank Math now generate the base file automatically, with the whole implementation typically taking under 30 minutes. If your site is a storefront, a services business, or general marketing content with no developer audience, the assessment is that llms.txt won’t hurt anything if added, but there’s no evidence it helps either, and the time is better spent on markup, page structure, or content depth that has a documented effect on both classic and AI-driven search.
*Source: Llms.txt V2 Adds Formal Markdown Linking For AI Agents, Search Engine Journal*